Reflexion Architecture: Self-Correction and Runtime Learning for AI Agents
Explore the five components of Reflexion, verbal reinforcement and episodic memory, with code repair and multi-step reasoning examples, safe execution and evaluation.
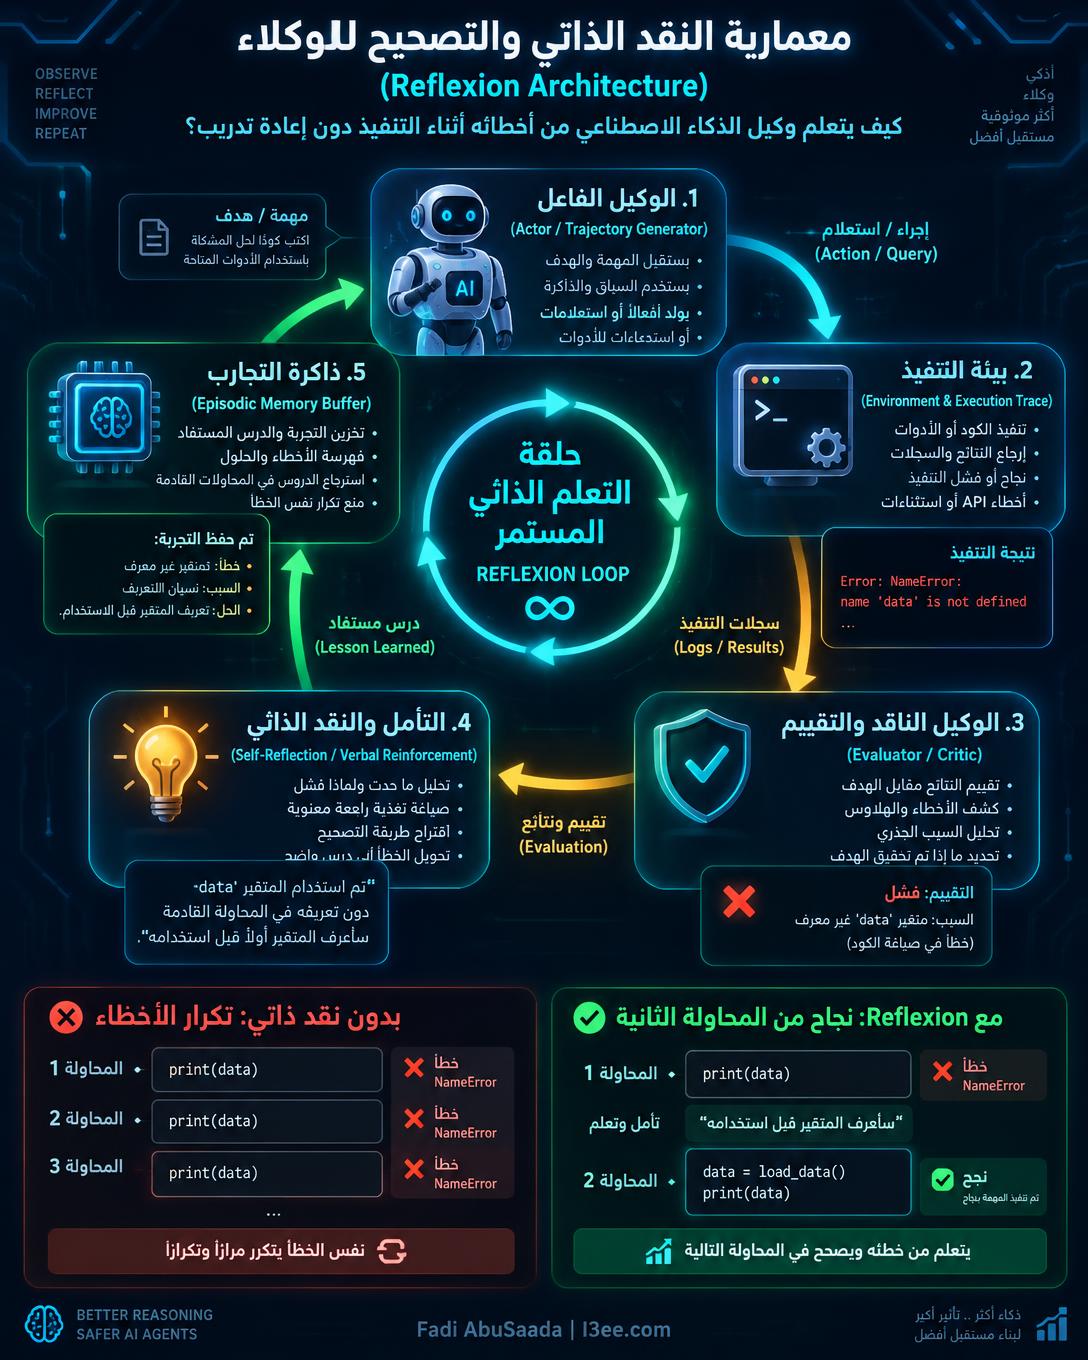
An agent writes code, runs it, sees a failure—and then submits almost the same code again. More attempts do not necessarily mean more progress. The missing piece is not another generation call, but a mechanism that turns observable failure into a specific lesson and makes that lesson available before the next decision.
Reflexion, introduced by Shinn and colleagues in “Reflexion: Language Agents with Verbal Reinforcement Learning,” organizes this mechanism around execution, evaluation, textual self-reflection and episodic memory. The five components in the supplied infographic are an engineering view of this loop: Actor, Environment and Execution Trace, Evaluator or Critic, Self-Reflection, and Episodic Memory Buffer.
1. Actor: generate a trajectory, not just an answer
The Actor receives the task, constraints, current observations and selected lessons from earlier trials. It produces a trajectory: a sequence of tool calls, intermediate artifacts and decisions leading to an answer or a state change. A coding trajectory may include reading an interface, editing a function and running tests; a research trajectory may include searches and evidence extraction.
Keep the task contract outside editable reflections. A lesson may suggest validating an input before parsing it; it must not override permissions or redefine success. The Actor can use a ReAct-style interaction pattern, but Reflexion does not require one particular prompting format or a separate model for every role.
2. Environment and Execution Trace: ground feedback in evidence
The environment executes authorized actions and returns observations: compiler diagnostics, test failures, API responses, retrieved documents or state transitions. The trace records what was requested, what actually ran and what changed. Without that trace, a fluent reflection can invent a cause that never occurred.
- →Record task and trial identifiers, artifact versions, tool names, sanitized arguments, results and evaluator verdicts.
- →Reset temporary files and mock state between trials so a failed attempt does not contaminate the next evaluation.
- →Separate transient infrastructure failures from mistakes in the solution. A timeout may justify backoff, not a rewritten algorithm.
- →Run generated code in an isolated environment with restricted network access, bounded resources and no production secrets.
3. Evaluator / Critic: decide what failed and why
The Evaluator measures the trajectory against explicit acceptance criteria. Prefer deterministic signals when available: unit tests, type checks, schema validation, exact constraints or an environment reward. A model-based critic can assess clarity, completeness or evidence quality, but its opinion is not equivalent to an execution result.
A useful evaluation separates observation, diagnosis and uncertainty. “Test invoice_duplicate failed: total was counted twice” is evidence. “The aggregation probably lacks idempotency” is a hypothesis. “The solution is bad” is too vague to guide repair. When tests and critic disagree, preserve the conflict rather than asking the Actor to trust the most confident sentence.
4. Self-Reflection: turn a verdict into verbal reinforcement
The Self-Reflector reads the task, failed trajectory and evaluator feedback, then produces a compact explanation of the mistake and an actionable strategy for the next trial. Verbal reinforcement is this natural-language signal. It is not gradient-based reinforcement learning: the next attempt is conditioned on text rather than an optimizer updating model parameters.
- →Observation: point to the specific failed test or missing evidence.
- →Cause: state a supported cause, or label it as a hypothesis needing verification.
- →Correction: describe a changed decision or action, not “try harder.”
- →Validation: specify the check that would demonstrate the correction worked.
- →Scope: state when this lesson applies and when it does not.
Do not equate self-reflection with exposing private chain-of-thought. Operational reflections can be short, auditable summaries grounded in observable actions. They need to tell the next attempt what to change, not reproduce every hidden reasoning step.
5. Episodic Memory Buffer: carry the lesson into the next trial
The buffer stores reflections from previous trials and supplies relevant entries to the Actor. In a minimal implementation, this is a bounded list attached to the task prompt. In a larger system, it can be a persistent store with task scope, provenance, timestamps and retrieval. Persistence across unrelated tasks is an application choice, not an automatic property of Reflexion.
Store hypotheses separately from validated lessons. Deduplicate repeated failures, retire contradicted advice and retrieve by task relevance rather than recency alone. Unbounded memory increases cost and may bury the useful signal; overly broad lessons can cause a correct solution to adopt the wrong fix.
Reflexion versus naive retry loops
A naive retry resubmits the same task, perhaps with a different sampling seed. A feedback-aware retry might append an error message. Reflexion goes further by analyzing the trajectory, extracting a strategy and retaining that strategy for the next attempt. The boundary is architectural, not a magic name: a retry system that already does all of this is effectively implementing a reflection loop.
Ordinary retries are still appropriate for transient network failures. Reflection is more useful when the failure reveals a wrong assumption, missing prerequisite or flawed decomposition. If an action sends an email, charges a card or changes a real system, repeating it is not safe merely because the model wrote a lesson: require idempotency, approval or a rollback plan.
Example A: from NameError to complex code repair
The infographic starts with print(data) failing because data is undefined. Repeating print(data) reproduces the error. A useful reflection says: “Initialize data from the intended source before reading it; confirm that loading succeeds.” The next trial might run data = load_data() before print(data). This is an illustrative correction, not a guarantee: load_data must exist and return a suitable value.
Now consider an agent implementing an invoice importer with pagination, duplicate detection and retryable API calls. Its first version passes the happy-path test but double-counts invoices when a page is fetched again after a timeout. The evaluator reports the duplicate total and the trace shows repeated invoice identifiers. Simply regenerating the importer may change style without repairing the invariant.
- →Critic: the same stable invoice identifier contributes to the total more than once after replay.
- →Reflection: deduplicate by stable identifier before aggregation; make pagination retries safe; verify that distinct invoices sharing an amount are not accidentally merged.
- →Next Actor trial: implement identifier-based deduplication, preserve page traversal and add duplicate-page plus distinct-identifier tests.
- →Validation: rerun the original failure and the full regression suite. Do not change the expected result merely to make the test pass.
Example B: repair a multi-step reasoning plan
Suppose a research task asks which eligible supplier has the lowest total delivered cost. The Actor selects the lowest unit price but overlooks transport costs, a quantity threshold and the delivery deadline. A confident final answer conceals an incomplete decomposition. The evaluator compares the answer with the stated constraints and flags the missing cost terms and eligibility evidence.
The reflection should prescribe an evidence-backed plan: first filter by deadline and quantity requirements; then collect price, transport and applicable charges for each remaining supplier; compare totals for the same quantity; cite sources and mark missing data. On the next trial, the Actor gathers the missing information rather than merely rephrasing its conclusion. A lesson about checking eligibility before optimizing cost transfers only to tasks with comparable constraints.
A bounded runtime orchestration contract
- →Initialize the task contract and a clean environment; retrieve a small set of relevant, trusted lessons.
- →Let the Actor execute within its tool permissions and collect a redacted trajectory.
- →Evaluate the artifact and state against acceptance criteria. Stop on verified success.
- →On a repairable failure, create an evidence-grounded reflection and save it with provenance and validation status.
- →Start the next trial from a controlled state with the lesson in context; compare whether the same failure recurs.
- →Stop at the configured attempt, time or cost budget, on repeated unchanged failure, or on a non-repairable safety condition. Escalate with evidence.
Separate responsibilities even if one underlying model serves multiple roles. The Critic must not silently weaken the acceptance criteria, and a failed trial must not overwrite the best verified artifact. For costly actions, use previewable plans and mock execution before any approved real-world commit.
Failure modes: a convincing lesson can still be wrong
An unreliable evaluator can reward an incorrect answer; a reflector can overfit one visible test; stale memory can apply an outdated rule. A malicious document or tool response can also try to become a durable “lesson.” Treat external observations as untrusted data and never promote them into higher-priority instructions or tool permissions.
- →Use held-out evaluation cases unavailable to the repair loop to detect test overfitting.
- →Attach source traces and scope to memory entries; review or quarantine suspicious reflections.
- →Redact secrets and personal data before logging or storing lessons; define retention and deletion policies.
- →Require independent checks for security-sensitive corrections and preserve least-privilege execution.
- →Watch for repeated identical diagnoses, growing memory and rising latency without verified progress.
Measure learning, not the number of reflections
Compare the same base model and task set under the same total budgets: one attempt, ordinary retries, error-feedback retries and a reflection-memory loop. Track verified success, attempts to success, repeated-failure rate, regression rate, tokens, tool costs and end-to-end latency. Report cases that never succeed, not only successful repairs. An ablation without memory or without reflection helps identify which part actually contributes.
The original research evaluates Reflexion on decision-making, reasoning and programming tasks; those results motivate the architecture but do not guarantee a gain on your workload. Runtime adaptation is strongest when feedback is informative and the environment allows safe repeated trials. Where evaluation is weak or every action is irreversible, extra reflection can add risk and cost instead of competence.