Compound AI Systems: Why System Architecture Beats the Monolithic Model
Why reliable AI products are engineered as systems, not oversized prompts: task routing, specialized models, deterministic tools, retrieval, verification, observability, and the production trade-offs behind compound AI architecture.
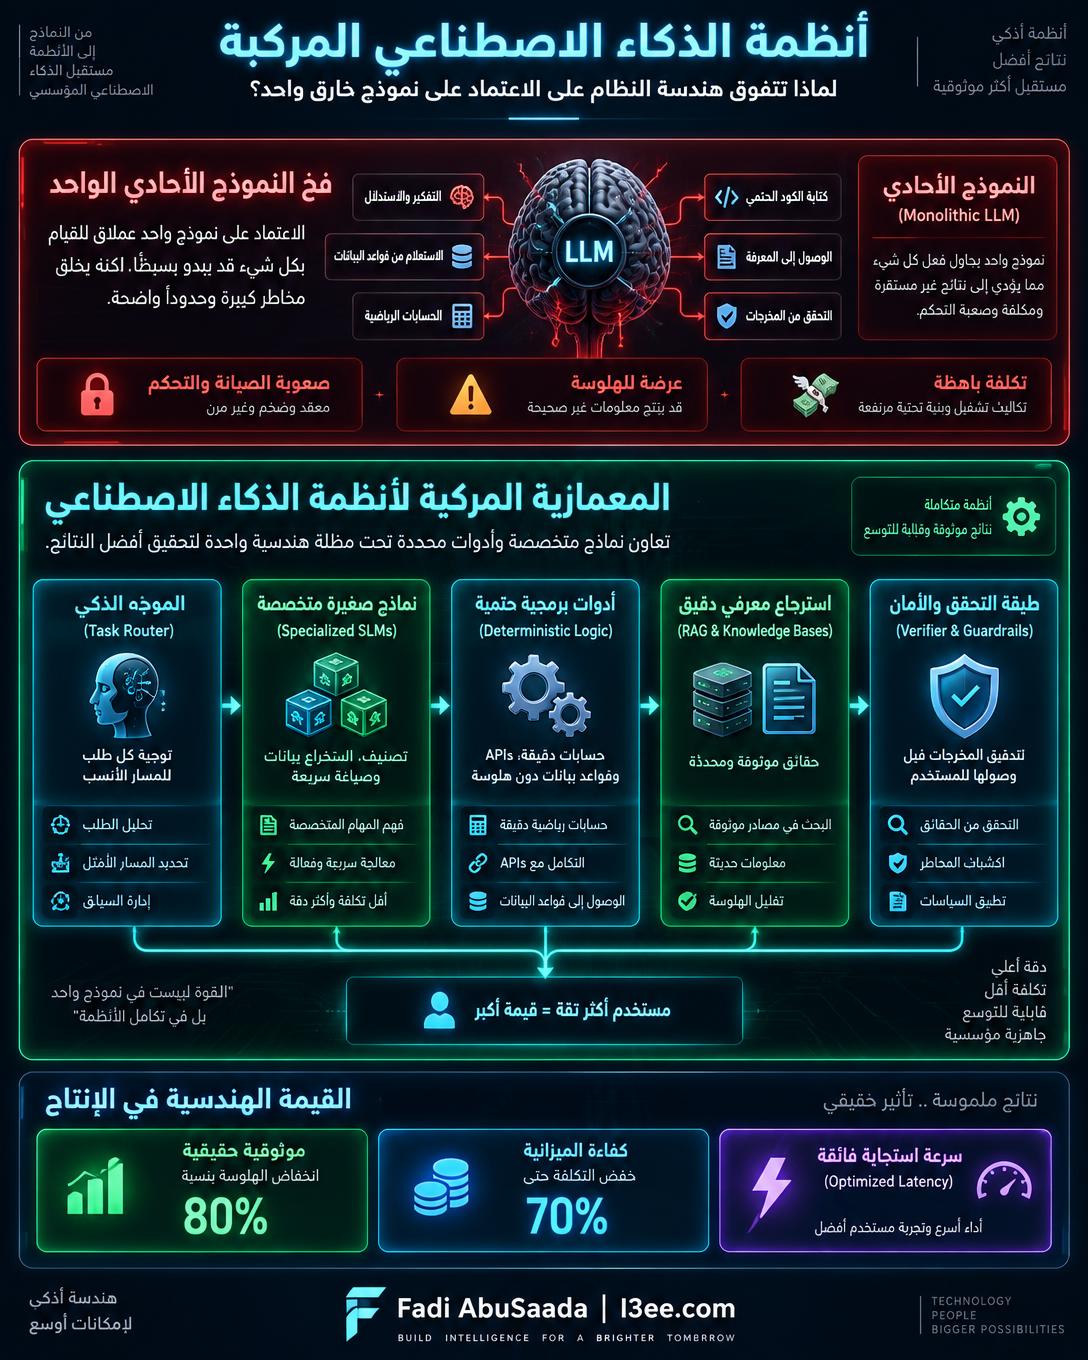
The first generation of generative-AI products was built around a seductive idea: if the model is powerful enough, give it the entire problem in one prompt and let it do everything. It should understand intent, retrieve facts, calculate, write code, follow policy, verify its own answer, and format the final response. That approach produces impressive demos. Under production traffic, it produces an expensive black box whose failures are difficult to predict, locate, or repair.
A compound AI system takes the opposite view. Intelligence is not one model call; it is a workflow in which models, retrieval systems, deterministic software, tools, and validators each perform the part they are best suited to perform. The model remains important, but system architecture determines whether its intelligence becomes reliable, economical, and safe enough to operate at scale.
1. The Monolithic Model Trap
A monolithic LLM is asked to absorb every concern into its weights and context window. The same probabilistic engine classifies the request, recalls knowledge, executes arithmetic, interprets business rules, and judges its own output. This concentrates capability, but it also concentrates risk.
- →Knowledge is frozen or weakly grounded — the model may answer from stale training data even when an authoritative source exists
- →Deterministic work becomes probabilistic — calculations, schema validation, and policy checks are less reliable when expressed as natural-language instructions
- →Every request pays the premium — a large general model handles simple classification and extraction tasks that smaller models or code could solve faster
- →Self-verification is correlated — asking the same model to critique its answer often reproduces the assumptions that caused the original error
- →Failures are opaque — one final response does not reveal whether routing, retrieval, reasoning, tool use, or validation failed
2. The Compound Architecture: A Pipeline of Specialists
A compound system decomposes the request into explicit stages. Each stage has a narrow contract, measurable inputs and outputs, and an implementation chosen for the job rather than for architectural uniformity.
- →Task router — classifies intent, estimates complexity and risk, then selects the cheapest capable path instead of sending every request through the largest model
- →Specialized models — compact models handle extraction, classification, translation, or domain-specific reasoning with lower latency and cost
- →Deterministic tools — calculators, APIs, databases, compilers, and business-rule engines execute operations that must be exact and reproducible
- →Retrieval layer — vector, keyword, graph, or SQL retrieval supplies current and traceable evidence rather than relying on parametric memory
- →Verifier and guardrails — an independent layer checks grounding, policy compliance, data leakage, output structure, and confidence before delivery
3. Why Decomposition Improves Quality and Economics
The gain is not that every component is smarter than a frontier model. The gain is that the system routes uncertainty to models and certainty to software. A model decides which calculation is needed; a calculator performs it. A retriever finds the governing policy; a verifier confirms that every important claim is supported by it. This division reduces the number of jobs for which fluent guessing is accepted as execution.
- →Higher reliability — critical claims can be grounded in sources and checked by a component that did not generate them
- →Lower cost — model cascades reserve expensive reasoning for ambiguous cases while routine requests follow cheaper paths
- →Lower latency — independent retrieval and checks can run in parallel; fast paths bypass unnecessary stages
- →Replaceability — a model, index, or validator can be upgraded without rebuilding the entire product
- →Better governance — permissions, data boundaries, and audit records live in explicit software rather than inside a prompt
4. Feedback Loops, Observability, and Evaluation
Decomposition only creates value when the seams are observable. Production traces should record the selected route, retrieved evidence, tool arguments, model and prompt versions, verifier decisions, token use, latency, and final user outcome. This turns a vague complaint — ‘the AI was wrong’ — into an actionable diagnosis at a specific stage.
- →Evaluate components and the whole system — retrieval recall, router accuracy, tool success, groundedness, policy compliance, and end-to-end task completion require separate metrics
- →Capture corrections — user edits, rejected answers, and human approvals become labelled feedback for routing rules, retrieval indexes, prompts, and fine-tuning
- →Use confidence as control flow — low-confidence outputs should trigger stronger retrieval, a larger model, a second verifier, or human review
- →Version every dependency — a model upgrade can improve reasoning while reducing tool-call accuracy; traces must make regressions attributable
5. The New Failure Modes
Compound systems are not free reliability. They exchange one opaque failure surface for several visible ones. A wrong route can send the request to an incapable model; poor retrieval can poison excellent reasoning; retries can multiply cost; and independently acceptable components can produce a weak end-to-end result when their contracts do not align.
- →Error compounding — a 95% reliable stage repeated across five dependent stages does not produce a 95% reliable workflow
- →Orchestration complexity — timeouts, retries, fallbacks, idempotency, and partial failure become first-class engineering concerns
- →Latency creep — sequential model calls can erase quality gains unless work is parallelized and budgets are enforced
- →Evaluation debt — optimizing each component in isolation can hide a decline in the user-visible task outcome
6. The Engineering Decision Matrix
- →Use one model when the task is low-risk, self-contained, inexpensive, and easy for a human to verify — drafting, brainstorming, or simple transformation
- →Add retrieval when answers depend on private, current, or citable knowledge
- →Add deterministic tools when exact calculations, transactions, structured queries, or irreversible actions are involved
- →Add routing and model cascades when traffic mixes simple requests with a smaller set of difficult or high-risk cases
- →Add independent verification and human approval when an error can create legal, financial, security, or safety impact
- →Build the full compound architecture when reliability, auditability, cost control, and continuous improvement matter simultaneously
"The moat is not one model. It is the system that knows which model to call, what evidence to provide, which tools to trust, and when not to answer."
The Architectural Takeaway
A monolithic model optimizes for capability in one place. A compound AI system optimizes for the outcome across the entire path. The strongest production architecture is rarely the one with the most model calls; it is the smallest observable workflow that assigns each responsibility to the component that can perform it most reliably. Start with one model, measure where it fails, then introduce routing, retrieval, tools, and verification only where evidence justifies the complexity. System design wins not by making the model less important, but by making intelligence operational.